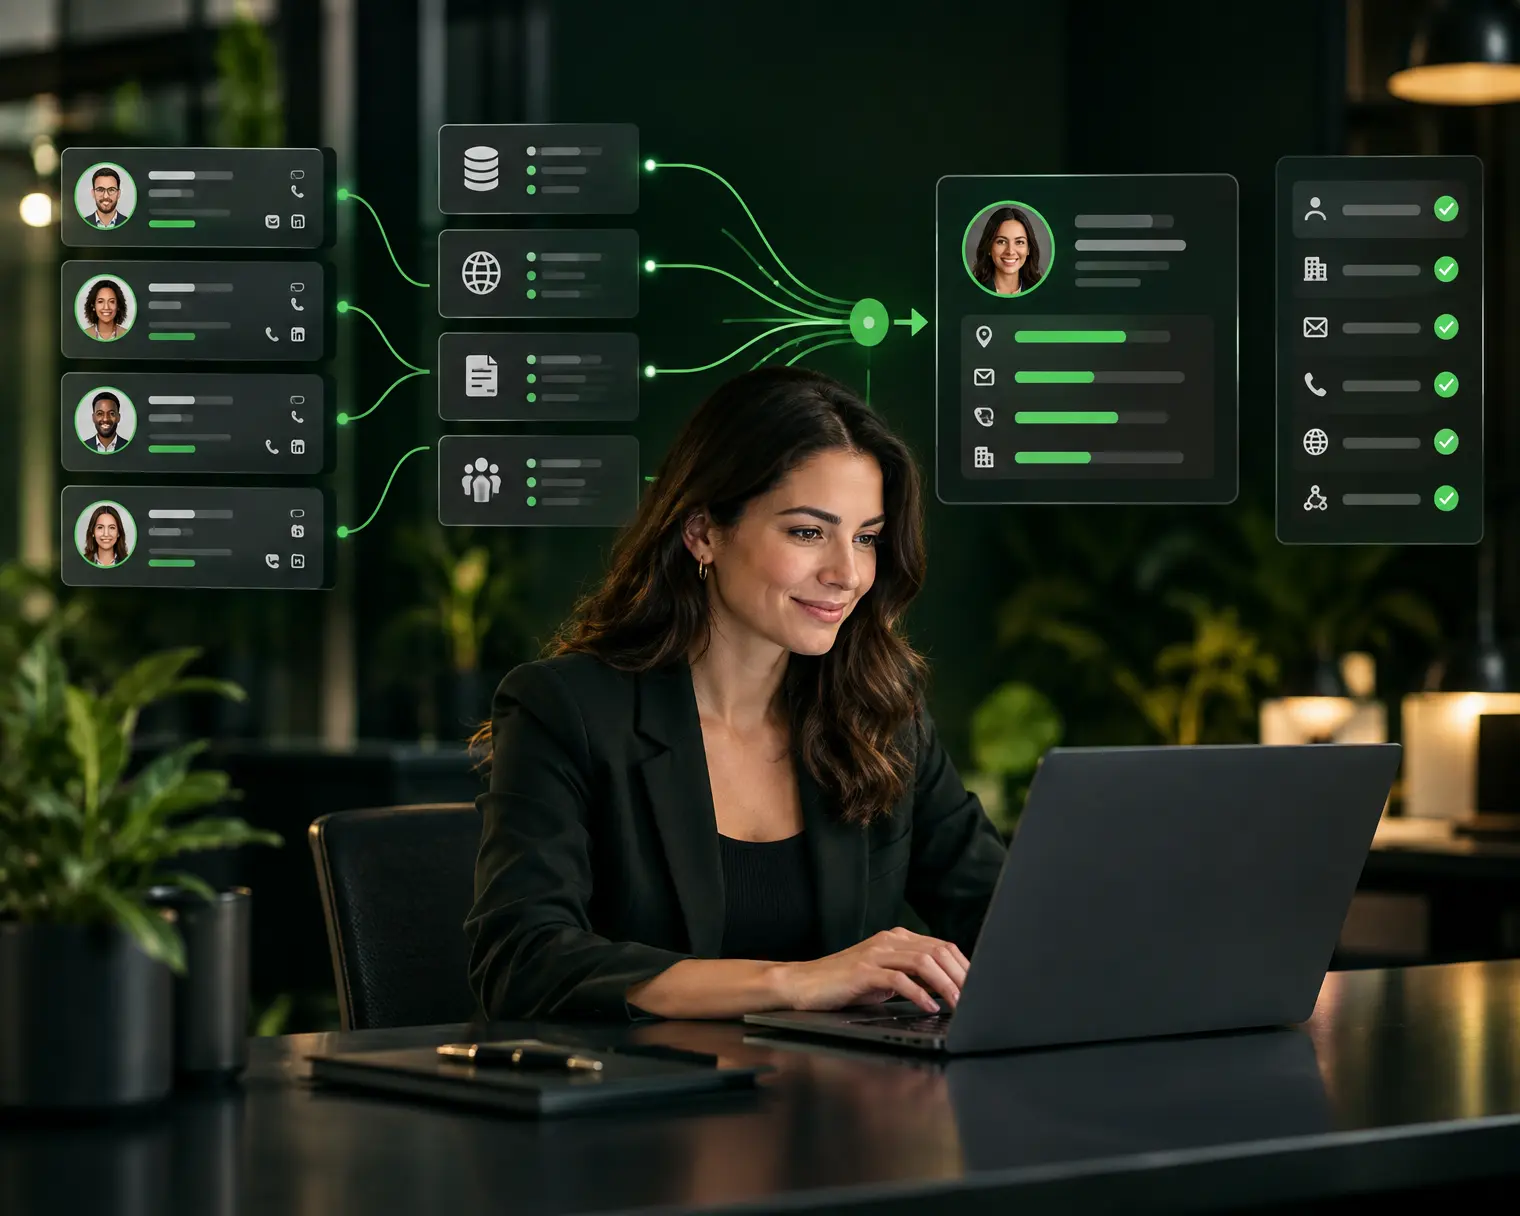

A contact enrichment API is a REST endpoint that accepts a partial identifier, email address, LinkedIn URL, or name + company, and returns a completed contact profile including verified email, direct phone, title, seniority, department, LinkedIn URL, work history, and social profiles. It differs from a broader lead enrichment API by focusing specifically on the person layer rather than company firmographics: the input is often just an email or LinkedIn URL, and the output is the human profile behind it. Contact enrichment APIs power CRM auto-fill (when a new record is created from a business card scan or a signup form), sales sequence personalization, and identity resolution across marketing databases. Match rates run 55-75% single-vendor and 85-95% via waterfall stacking. Unlike broader B2B contact data guides, this article focuses on the API layer: which endpoints exist, how to integrate, latency and cost expectations, and 3 FAQ.
For a CTO, RevOps engineer, product engineer, or growth engineer wiring contact enrichment into a product signup, CRM, or sales workflow, this article covers the API surface, integration patterns, and vendor selection.
On the agenda:
- What a contact enrichment API delivers vs a company enrichment API
- Standard endpoints and payload shapes
- Input types (email, LinkedIn URL, name + company) and match rates
- Integration patterns: synchronous, async, webhook, batch
- 5 provider APIs compared
- Latency, cost, and rate limit expectations
- Security, PII, and GDPR handling
- 3 FAQ (input quality, match rate, cost per contact)
Key takeaways:
- Definition: API returning enriched person data from a partial identifier
- Common inputs: email, LinkedIn URL, or name + company_domain
- Common outputs: verified email, phone, title, seniority, department, LinkedIn, work history
- Response time: 200-500 ms typical, 800 ms-2s waterfall
- Match rate: 55-75% single-vendor, 85-95% waterfall 3-4 sources
- Authentication: API key (Bearer) or OAuth 2.0
- Rate limits: 60-600 calls/min on paid, 5-25/min free
- GDPR: legitimate interest + suppression list API required for EU targets
1. Contact enrichment API vs company enrichment API
- Contact enrichment API: input is a person identifier (email, LinkedIn URL, name + domain), output focuses on the individual (title, phone, email verified, seniority)
- Company enrichment API: input is a domain or company name, output focuses on firmographics (employees, revenue, industry, tech stack, funding)
Many vendors combine both under a single /enrich endpoint that mixes person + company payload; others split them into /person/enrich and /company/enrich. The API design choice affects rate limits and cost accounting.
Where contact enrichment fits
- CRM auto-fill: new record created from a form submission or manual entry, API called with just the email → CRM record completed with title, phone, LinkedIn
- Cold outreach personalization: SDR imports a LinkedIn list → API called for each URL → email + title returned for sequence templating
- Identity resolution: marketing database has
email + timestamp + product_signup, contact enrichment API reveals the human decision-maker behind the anonymous email
2. Standard endpoints and payloads
/contact/enrich (or /person/enrich)
Input can be one of three identifier types:
By email:
By LinkedIn URL:
By name + company:
Output typically:
{
  "contact": {
    "email": "marie.dupont@acme.com",
    "email_status": "verified",
    "email_confidence": 95,
    "phone": "+33 6 12 34 56 78",
    "phone_confidence": 82,
    "first_name": "Marie",
    "last_name": "Dupont",
    "title": "VP Marketing",
    "seniority": "vp",
    "department": "marketing",
    "linkedin_url": "https://linkedin.com/in/marie-dupont",
    "twitter_handle": null,
    "github_handle": null,
    "location": "Paris, France"
  },
  "employment": {
    "company_name": "Acme Corp",
    "company_domain": "acme.com",
    "start_date": "2023-06-01",
    "is_current": true
  },
  "meta": {
    "confidence_score": 92,
    "sources_matched": ["proprietary_db", "linkedin_public", "smtp_verified"],
    "credits_used": 1,
    "response_time_ms": 380
  }
}
/contact/verify
Input: email. Output: valid, invalid, catch_all, disposable, role_based (like info@, sales@), or unknown.
/contact/find
Input: name + company. Output: predicted email + confidence. This is pattern matching + probabilistic scoring, not verified enrichment.
/contact/bulk
Input: array of up to 100-1,000 identifiers. Output: async job ID → results polled or delivered via webhook.
3. Input types and match rate impact
The input identifier shapes match rate substantially:
- Email input: 90-95% match if email is valid (you already have the verified anchor; API just fills in title, LinkedIn, phone)
- LinkedIn URL input: 85-90% match (LinkedIn is the highest-precision anchor; if the URL exists, most vendors find the profile)
- Name + company_domain: 55-75% match (ambiguous names, common titles, no unique anchor)
- Name only, no company: 20-40% match, mostly guesses
Practical implication: if your CRM has emails but not phones/titles, run /contact/enrich by email, you’ll get ~90% completion. If you only have LinkedIn profile scrapes, expect ~85%. If you only have names from a conference badge scanner, waterfall is essential.
4. Integration patterns
Pattern 1: Signup real-time
User submits form with email → /contact/enrich called synchronously → CRM record enriched before the user hits the thank-you page. Best under 500ms end-to-end; use vendor with p95 < 700ms.
Pattern 2: Async post-signup
User submits form → thank-you page shows immediately → queue job → API called → CRM PATCH-updated 5-30 seconds later. No user-facing latency; more robust to API downtime.
Pattern 3: Bulk CRM cleanup
Weekly cron: query CRM for records with email IS NOT NULL AND title IS NULL → call /contact/bulk → poll for completion → import. Good for legacy record cleanup or freshly imported lists.
Pattern 4: Webhook-triggered
Some CRMs (HubSpot, Salesforce) support outbound webhooks on record creation. Point the webhook at a receiver that calls the enrichment API → updates via the CRM’s PATCH endpoint. Serverless (AWS Lambda, Cloudflare Workers) is a good fit here.
5. 5 provider APIs compared
Positioning only.
Clearbit (HubSpot)
Strong on email → full profile enrichment. Native HubSpot integration means auto-enrichment happens without custom code. Best fit for US-heavy datasets.
Apollo.io
Broad contact database, developer-friendly API, GraphQL and REST. Combines search + enrichment. Free tier available.
Cognism
European positioning, GDPR-compliant certified base, active suppression list API. Strong on EMEA phone numbers.
Lusha
Focused on person + phone enrichment. Simple API, quick to integrate. Chrome extension companion for manual use.
Zeliq
450 million contact base, waterfall enrichment built into a single API endpoint (no orchestration of 3-4 vendors needed), integrated email verification, multichannel sequences as follow-on. European positioning, GDPR by design, native suppression endpoint.
Selection grid
- HubSpot CRM ecosystem, US-heavy → Clearbit
- Broad DB with sourcing + enrichment self-serve → Apollo
- Strict GDPR + EMEA phones → Cognism
- Phone-heavy use case → Lusha
- Waterfall + European positioning → Zeliq
6. Latency, cost, rate limits
Latency
- Single-vendor call by email: 200-500 ms p50, 800 ms p95
- Single-vendor call by LinkedIn URL: 300-600 ms p50
- Single-vendor call by name + company: 400-800 ms p50
- Waterfall 3-vendor: p50 doubles, p95 triples
- Best-in-class vendors publish p50/p95/p99 in their docs; if not disclosed, assume p99 could be 5-30s
Cost
- Per-credit pricing: $0.10-0.50/contact typical
- Waterfall increases cost 1.3-1.8x per matched contact but adds 30-40 percentage points of match rate
- Bulk annual commits drop to $0.05-0.10/contact
Rate limits
- Free tier: 5-25 calls/min, 25-100/day
- Starter: 60-120 calls/min
- Growth: 300-600 calls/min
- Enterprise: 1,000+ calls/min or negotiated
7. Security and PII handling
Authentication
API Key (Bearer token) works for server-side; rotate keys quarterly and never commit to source. OAuth 2.0 required when accessing on behalf of a user (CRM integration accessing multiple tenants’ data). For SMTP-level verification steps that some enrichment APIs perform, the applicable protocol reference is IETF RFC 5321 (SMTP).
PII in transit
All API calls over TLS 1.2+. Vendor should be SOC 2 Type II certified for enterprise use, ISO 27001 preferred for European deployments.
GDPR
Vendors targeting EU should offer: - Documented legitimate interest process aligned with CNIL guidance on B2B prospecting - Suppression list API endpoint (POST an email/phone to opt out; vendor removes from base within 30 days) - Data Processing Agreement (DPA) signed with the customer - 3-year data retention policy on inactive contacts
The CNIL 2025 sanctions report shows €486 million in total enforcement, including SOLOCAL’s €900k fine for cold email without a sufficient legal basis, evidence that the missing-suppression risk is material for any B2B API consumer serving European ICPs.
8. Common pitfalls
Pitfall 1: Not caching
Same contact enriched twice = 2 credits burned. Cache enrichment result 30-90 days with a last_enriched_at timestamp. Re-enrich only after 90 days.
Pitfall 2: Trusting unverified emails
Some APIs return email_status: "unknown" on pattern-matched emails. Sending to these = 20-40% bounce. Always filter by email_status == "verified" before use.
Pitfall 3: Ignoring rate limits
Blasting 10,000 requests on a 300/min rate limit = 33 minutes of 429 errors. Use /contact/bulk or self-throttle to stay under the rate.
Pitfall 4: No suppression check pre-send
Even a verified enriched contact may have opted-out of your list historically. Query the vendor’s suppression API before every send, or maintain your own local suppression synced daily.
Pitfall 5: Single-vendor hard dependency
Vendor downtime or price hike kills the pipeline. Design fallback chain from day 1, or use a waterfall-native API layer.
Zeliq’s contact enrichment API
Zeliq exposes a contact enrichment API where waterfall across multiple data sources runs inside a single endpoint call. Combined with 450 million B2B contacts, integrated email verification, waterfall enrichment, and multichannel sequences, it lets a single engineer wire enrichment into a CRM in days instead of weeks. GDPR-native suppression endpoint included.
9. Implementation checklist
Before shipping a contact enrichment API integration to production:
- API key stored in secrets manager, not source code
-
Retry with exponential backoff on
429and500-503 - Response caching with 30-90 day TTL
- Metrics: p50/p95/p99 latency, match rate, cost per contact
- Dead-letter queue for permanent failures
- Suppression list check before outbound send
- DPA signed with vendor if handling EU data
- Documented legitimate interest for each ICP the API touches
10. Frequently asked questions
What’s the difference between input types for a contact enrichment API?
Email input delivers the highest match rate (~90-95%) but requires an already-valid email; LinkedIn URL input delivers ~85-90% match with public URL as anchor; name + company_domain drops to 55-75% due to ambiguity. The reason is anchor precision: an email is a unique global identifier that maps to exactly one person, so the API only needs to enrich around that anchor (title, phone, LinkedIn). A LinkedIn URL is nearly as unique (each profile ID is globally unique), so match stays high. Name + company_domain introduces ambiguity: multiple John Smiths can work at IBM.com, so the API has to guess or return multiple candidates. Practical guidance: (1) If your source data is email-first (product signups, form fills, downloaded lead lists), send email to the API, expect 90%+ completion with title, phone, LinkedIn. (2) If your source is LinkedIn (Sales Navigator export, LinkedIn scraper), send linkedin_url, expect 85-90% completion with email and phone. (3) If your source is a conference badge scan or business card OCR with just names, expect 55-75% match single-vendor, 85-90% waterfall. Some APIs support hybrid input (name + linkedin_url or email + name) which lifts match by 5-15 points. Test your specific vendor with your specific input mix before assuming their published benchmarks apply.
What is a realistic match rate benchmark for a contact enrichment API?
55-75% for single-vendor on typical B2B ICPs by name + company_domain; 90-95% with email input; 85-95% with waterfall 3-4 vendors across any input type. Match rate depends on: (1) input identifier precision, (2) vendor’s geographic coverage of your ICP (US-heavy vendors underperform on APAC/EMEA), (3) vendor’s data freshness on your target function/seniority (senior roles get updated more often; niche engineering titles lag), (4) whether the vendor verifies emails synchronously or returns pattern guesses. Concrete measurement: run 500 in-ICP contacts through the API, count records where email_status == "verified", that’s your ground-truth match rate, ignoring vendor marketing benchmarks. Anything below 60% single-vendor on name + company input suggests wrong vendor for your geography. Anything below 85% on email input suggests the vendor is returning unverified matches inflating their nominal match rate. For B2B teams enriching more than 5,000 contacts/month, waterfall (3-4 vendor fallback) is essentially mandatory to reach 85%+ aggregate match, but building it in-house takes 2-3 weeks of engineering. Waterfall-native API vendors (Zeliq and similar) provide it as a single-endpoint service with 3-5 day integration time.
What does a contact enrichment API cost per contact?
$0.05-0.50 per verified enriched contact depending on volume, plan tier, and enrichment depth (basic email vs full profile including phone). Cost tiers: (1) Pay-as-you-go / free tier: $0.20-0.50/verified contact effective; (2) Starter monthly ($100-500/month): $0.15-0.30/contact; (3) Growth monthly ($500-2,000/month): $0.10-0.20/contact; (4) Enterprise annual ($20k+/year): $0.05-0.10/contact. Enrichment depth matters: some vendors charge 1 credit for basic (email + title), 2-3 credits for full (email + phone + LinkedIn + tech stack). Waterfall math: a match on vendor A costs 1 credit; a match on vendor C means A + B + C were called and burned 3 credits, waterfall aggregate cost is 1.3-1.8x single-vendor per matched contact, but delivers 30-40 percentage points more match, so cost-per-verified-contact often stays similar or lower. Beyond direct API cost, factor engineering time (2-3 weeks to build waterfall vs 3-5 days with waterfall-native vendor), monitoring overhead ($200-500/month engineering time), and vendor lock-in cost. Break-even between DIY waterfall and waterfall-as-a-service is typically at 10k-50k enriched contacts/year, below that, waterfall-native vendor is cheaper; above, DIY orchestration starts to pay off.
11. Conclusion: 3 actions to run
Prototype with a free-tier API within 7 days. Test end-to-end on 20-50 real ICP contacts. Measure match rate and latency.
Benchmark real match rate within 15 days. 500-contact sample, mix of input types (email, LinkedIn, name+domain). Anything below 60% by name+domain or 85% by email means vendor is a poor fit.
Implement caching and rate-limit handling before production within 30 days. Skip these and you’ll burn 2-3x more credits than needed and see production
429cascades on first traffic spike.
One API endpoint, waterfall built-in, 85-95% match rate
Zeliq combines 450 million B2B contacts, waterfall enrichment through a single API, integrated email verification, and multichannel sequences. GDPR-native suppression endpoint. Free credits included to test on your ICP.
Try for freeAnd if you want a contact enrichment API with waterfall built in and GDPR-native suppression, try Zeliq for free: sourcing, enrichment, and multichannel sequences via API, no credit card required.